Llama Made Crystal Clear · chapter 4: What Llama Actually Costs: Local vs Hosted
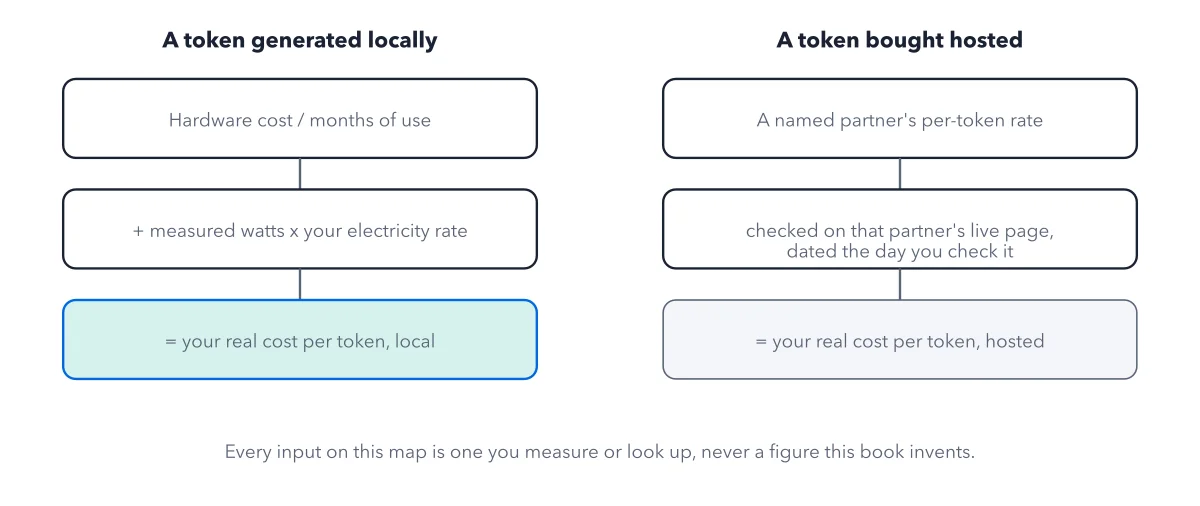
The meter map, tracing a locally generated token and a hosted token to their real cost...
2026-10-12
Below: the paragraph from the book that builds this idea, then the diagram itself (Figure 4.1), and a recap. About a minute of reading.
A GPU's power draw at idle is very different from its draw under a sustained inference load, and a spec sheet's peak wattage figure describes neither of those conditions particularly well. The only reliable way to know what your setup actually costs in electricity is to measure it: a wall-meter device on the machine's power cable, or a software power-monitoring tool that reads directly from the GPU, run once at idle and once while actually generating tokens from a Llama model. Multiply the measured wattage by your own electricity rate, and you have a real number instead of a guess borrowed from a spec sheet that was never describing your actual workload.
Recap
- The idea: The meter map, tracing a locally generated token and a hosted token to their real cost sources.
- The picture: Figure 4.1, from chapter 4 ("What Llama Actually Costs: Local vs Hosted") of Llama Made Crystal Clear.
- Go deeper: the chapter builds this step by step, with recipes and sources at the end.
This diagram is one of many in Llama Made Crystal Clear.
Every chapter opens with the gist, draws the hard ideas, and ends with recipes and sources.
Get the book