Qwen Made Crystal Clear · chapter 6: Running Qwen on Your Own Hardware
Quantized file size against two common GPU VRAM sizes
2026-11-03
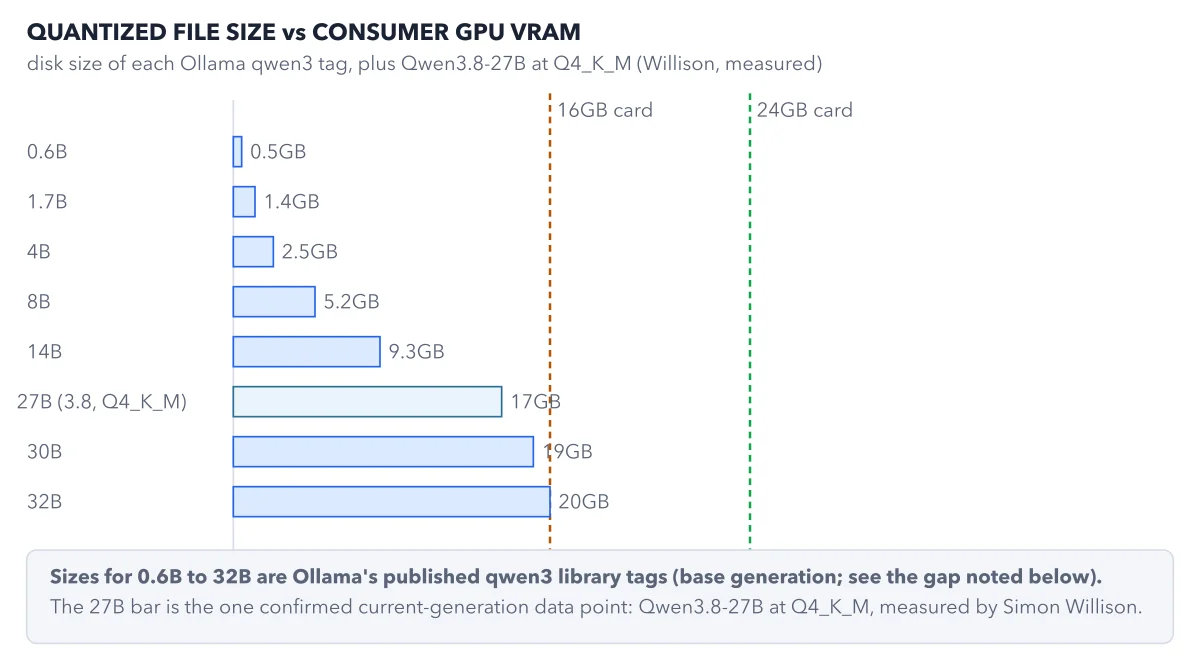
A bar that crosses a reference line needs headroom beyond the card's raw VRAM for context and runtime overhead, so treat "just barely fits" as "does not comfortably fit."
Below: the paragraph from the book that builds this idea, then the diagram itself (Figure 6.1), and a recap. About a minute of reading.
Start with a rule of thumb worth knowing before the table: a quantized model needs roughly its file size in video memory (VRAM) or unified memory, plus some headroom for the context window and the runtime itself. A 17GB weight file is not going to run comfortably on a 16GB card. Figure 6.1 plots the confirmed file sizes for the Qwen3 size ladder against the two GPU tiers the reader signal names most, 16GB and 24GB, so you can see at a glance where the headroom runs out.
Recap
- The idea: A bar that crosses a reference line needs headroom beyond the card's raw VRAM for context and runtime overhead, so treat "just barely fits" as "does not comfortably fit."
- The picture: Figure 6.1, from chapter 6 ("Running Qwen on Your Own Hardware") of Qwen Made Crystal Clear.
- Go deeper: the chapter builds this step by step, with recipes and sources at the end.
This diagram is one of many in Qwen Made Crystal Clear.
Every chapter opens with the gist, draws the hard ideas, and ends with recipes and sources.
Get the book